Wednesday, November 27, 2019
Guidelines on the long arms of the GDPR | Lexology
My comment: Interesting clarifications rg. the GDPR's territorial scope
(not only for New Zealand orgs)! > Guidelines on the long arms of the
GDPR lexology.com/library/detail… by @BuddleFindlay via @lexology #GDPR #DSGVO #DataProtection #DataPrivacy

Monday, August 18, 2014
When is the BEST time for a Data Quality Review? | Roshan Joseph (via LinkedIn)
Follow the LinkedIn discussion
My comment
While position 5 (NOW!) is the "correct" answer, I like to add "Merger & Acquisition" as a triggering event (variation / combination of pos. 1 to 4).
My comment
While position 5 (NOW!) is the "correct" answer, I like to add "Merger & Acquisition" as a triggering event (variation / combination of pos. 1 to 4).
With an upcoming M&A transaction, a data quality review prepares for
the audit that is an indispensable part of the due diligence. Both
(all) involved organizations should undergo a data quality review to
especially know about the mergability of the parties' data before taking
the final decision.
Monday, June 2, 2014
Tool to Track Which Databases Keep Customer Data | LinkedIn Group: Master Data Management Pros
Follow the LinkedIn discussion
My comment
I suggest you to use a professional data and process modeling tool suite.
The data modeling tool component will allow you to have an inventory of the data, i.e. which fields (particularly: customer data) reside in which database. Typical use of the data modeling tool could be:
Ideally, the tool suite will be integrated, i.e. database fields that are captured in the database reverse engineering step (using the data modeling tool) can be linked to the fields found in the analysis of the data flows (using the process modeling tool) and vice versa.
How you apply the modeling tool suite in detail will certainly depend on the mid and long-term goals of your organization, e.g. merging/replacing application systems, evaluating new software packages, changing platforms, going mobile etc.
Considering any of these targets combined with your initial question, I recommend you to check out the SILVERRUN Professional & Enterprise Series at www.silverrun.com . (In the spirit of full disclosure: I represent Grandite, the maker of the SILVERRUN tools.)
Please do not hesitate to contact me for further information directly, you will find my coordinates in "Contact Info" of my LinkedIn profile.
My comment
I suggest you to use a professional data and process modeling tool suite.
The data modeling tool component will allow you to have an inventory of the data, i.e. which fields (particularly: customer data) reside in which database. Typical use of the data modeling tool could be:
- Reverse engineer each database, i.e. automatic transfer of the database structure to a graphical/textual representation in the data modeling tool.
- (Since even (semantically) same fields will have different physical names in different databases...) Link synonyms to a common business name, e.g. "cust_name" and "cli_nam" could both represent "customer name".
- Add/modify any other crucial description that may be missing/incorrect.
- Integrate the database models into subject areas (A subject area will give you the synchronized business view of how e.g. a customer is - and perspectively should be - described in your organization, e.g. by customer first-name, customer family-name, customer date-of-birth, etc.)
Ideally, the tool suite will be integrated, i.e. database fields that are captured in the database reverse engineering step (using the data modeling tool) can be linked to the fields found in the analysis of the data flows (using the process modeling tool) and vice versa.
How you apply the modeling tool suite in detail will certainly depend on the mid and long-term goals of your organization, e.g. merging/replacing application systems, evaluating new software packages, changing platforms, going mobile etc.
Considering any of these targets combined with your initial question, I recommend you to check out the SILVERRUN Professional & Enterprise Series at www.silverrun.com . (In the spirit of full disclosure: I represent Grandite, the maker of the SILVERRUN tools.)
Please do not hesitate to contact me for further information directly, you will find my coordinates in "Contact Info" of my LinkedIn profile.
Sunday, May 25, 2014
How Does the Database Influence the Data Modeling Approach? | LinkedIn Group: Data Modeling
Follow the LinkedIn discussion
My comment
Based on the 4 primary steps suggested by Rémy [Fannader] (even considering that each of us may have slightly different convictions how to exactly mark off these steps against each other), the answer should be:
My comment
Based on the 4 primary steps suggested by Rémy [Fannader] (even considering that each of us may have slightly different convictions how to exactly mark off these steps against each other), the answer should be:
- Conceptual: not influenced by the target database
- Normalized logical: not influenced by the target database
- Denormalized logical: only influenced by the architecture / type of concepts that the database supports (doesn't support), e.g. nested table, materialized view
- Physical: completely influenced by the target database, e.g. physical names, database-specific storage parameters.
- Define, keep and maintain the above development levels
- Propagate (cascade) applicable modifications to the next level(s)
- Generate the DDL from the physical level.
Wednesday, May 7, 2014
How to Identify Parent / Child Role of an Entity in a Data Model Diagram Using "Information Engineering" Notation | LinkedIn Group: Data Modeling
Follow the LinkedIn discussion
My comment
Presuming that many-to-many relationships have been resolved as (binary) one-to-many relationships, there are two ways to communicate / express relationships, as
My comment
Presuming that many-to-many relationships have been resolved as (binary) one-to-many relationships, there are two ways to communicate / express relationships, as
- One-to-many relationships (or optional-one-to-one)
and/or
- Parent-child relationships [Child entity is the side of the relationship where the foreign key (constraint) will be added.]
However, provided that the integrity of the model has been positively
verified, these two ways are synchronized, i.e. the role of the parent
entity and of the child entity in a given one-to-many (or
optional-one-to-mandatory-one) relationship can be derived following the
rule "a mother can have many children, but a child has a maximum of one
mother".
The exception to this rule is an optional-one-to-optional-one
relationship which needs further specification about the parent or child
role of the participating entities.
For this latter case (or an interim state where the integrity of the model has not been verified yet), an Entity-Relationship diagram in Information Engineering notation only expresses the multiplicities of a relationship, but does not offer any "standard" indication about the parent / child role of an entity in a relationship.
Therefore, I suggest to use a data modeling tool that allows you to e.g. additionally display the name of the child direction close to the respective side of the relationship connector.
Once the model is verified and ready to generate foreign keys, the latter ones will graphically identify the child role of an entity in a relationship.
Sunday, March 9, 2014
Where Does the Line Between Data Modeler and DBA Fall? | LinkedIn Group: InfoAdvisors Members
Follow the LinkedIn discussion
My comment
My comment
I agree with your [Karen Lopez] "State of the Union" of Data Modeling as described in
your post related to this discussion. Leaving possible and probable
reasons aside that led to that state, I will here focus on your
question.
According to my observations, organizations have lost (and some never
adopted) the technique of targeted denormalization which bridges the gap
between the logical data model and the physical database design and
thus brings Data Modelers and DBAs together.
Based on a 3-level approach (I skip to discuss the steps that lead to a
Logical Data Model), responsibilities of Data Modelers, Developers and
DBAs can be assigned as follows:
- Logical Data Model: developed by Data Modelers / Data Administrators
- Transition Model: created by Developers and DBAs to denormalize the Logical Data Model according to the requirements of the application (create physical tables, views, indexes etc.)
- Physical Database Model: based on the Transition Model, DBAs add physical parameters allowing to completely generate the DDL for the (production) database
- Support denormalization of Logical Data Models
- Keep track of the lineage through the transformation process from logical tables/columns to database tables/columns
- Offer mechanisms that automatically propagate modifications from the Logical Data Model to subsequent levels (for modifications where the methodology is algorithmic and does not require human intervention)
- Offer mechanisms that allow to manually integrate modifications from the Logical Data Model to subsequent levels (for modifications where design decisions need to be taken)
- Include an interface that generates the script to create / alter the database (DDL) from the Physical Database Model.
How to model a ternary associative entity with a binary constraint? | LinkedIn Group: Data Modeling
Follow the LinkedIn discussion
My comment
My comment
Based on the information provided (and including your
later remark that this is just a hypothetical conceptual model to help
illustrate a concept), Option A shows the right model.
Additional relationships as of your options B and C are redundant since they do not add any semantics to the model that are not already expressed in Option A. Practical test: If you generate foreign keys, the model as of Option A will look as shown at http://www.silverrun.com/common/ternary-example-red.gif (using the notation "Information Engineering +").

The foreign keys in the table Diploma still allow a direct navigation to the table University and the table Degree (and vice versa).
Additional relationships as of your options B and C are redundant since they do not add any semantics to the model that are not already expressed in Option A. Practical test: If you generate foreign keys, the model as of Option A will look as shown at http://www.silverrun.com/common/ternary-example-red.gif (using the notation "Information Engineering +").
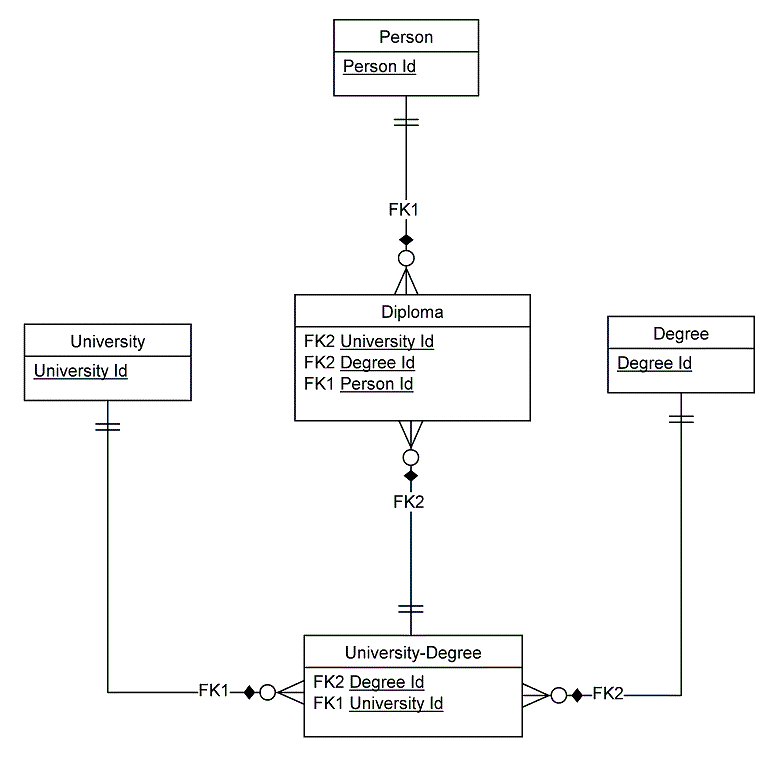
Click on image to enlarge it
The foreign keys in the table Diploma still allow a direct navigation to the table University and the table Degree (and vice versa).
Subscribe to:
Posts (Atom)